
Web Scraping with Selenium
A Python scraper using Selenium and BeautifulSoup to extract product listings from an e-commerce site.
Project Overview
A small introductory project exploring web scraping: automating a headless browser to page through an e-commerce site’s search results and extracting product names from the rendered DOM.
Technical Details
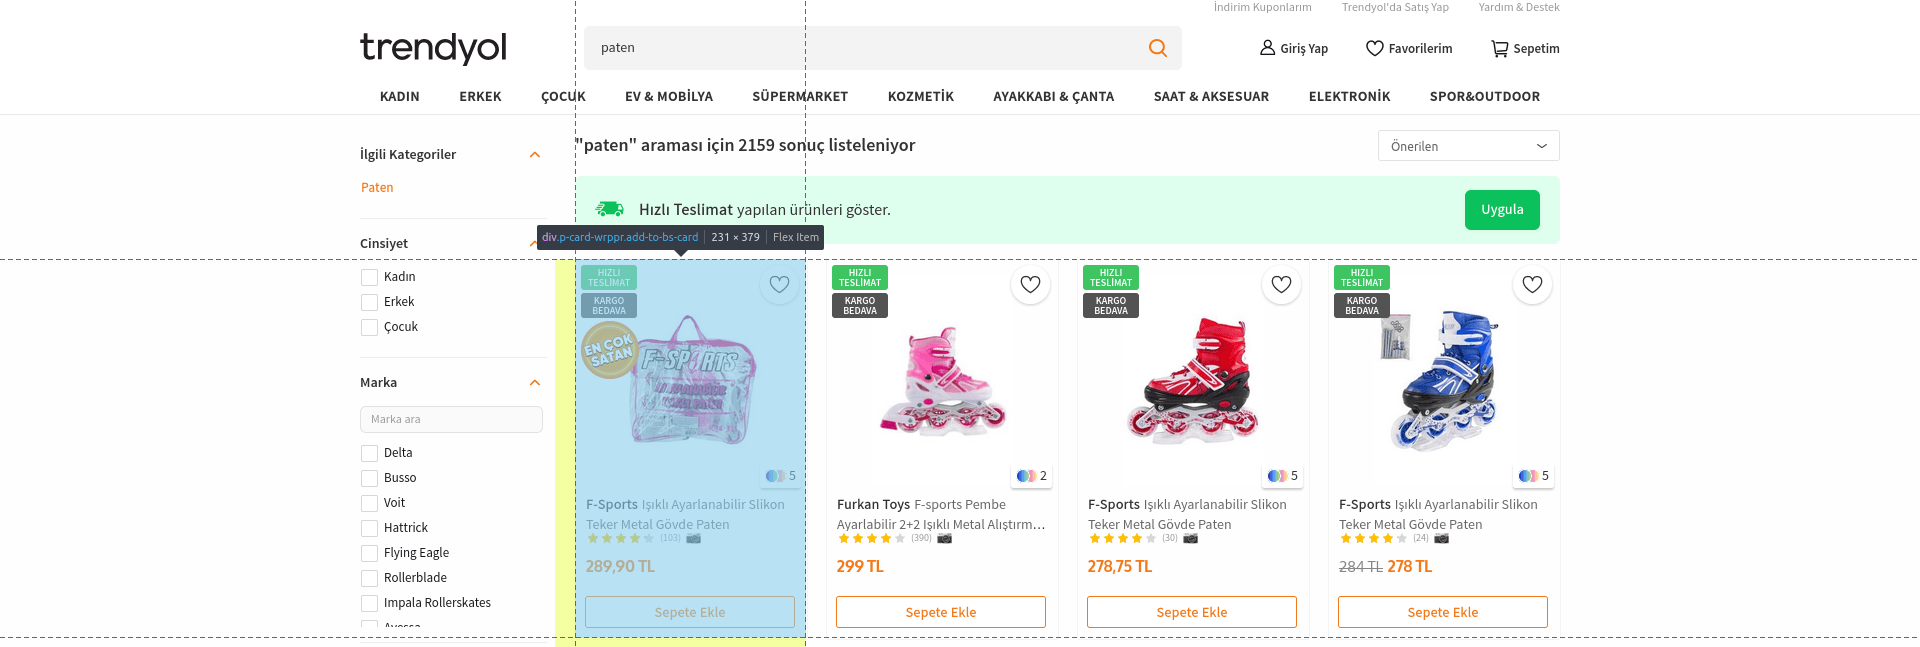
- Uses Selenium with the Firefox WebDriver to load and paginate through dynamically rendered search results (tested against Trendyol.com).
- Uses BeautifulSoup to parse the resulting page source and extract product name elements by their CSS class.
- Demonstrates identifying target elements via browser DevTools before writing the scraping logic.